We like to pretend the modern world runs on complex, decentralized wizardry. In reality, it runs on a handful of fragile choke points. When a single faulty software deployment or a backend authentication failure can instantly cascade into grounded commercial airliners, silent emergency dispatch lines, and paralyzed hospital networks, you stop looking at technology as an invincible shield. You start seeing it for what it actually is: a massive, single point of failure.
Major system crashes—whether triggered by catastrophic cybersecurity updates or widespread cloud server failures—aren't just annoying IT inconveniences. They are stark wake-up calls about the dangerous over-consolidation of global infrastructure.
The Illusion of Infinite Redundancy
Look closely at how global corporations operate. For decades, the dominant corporate playbook preached extreme centralization. Move everything to the cloud. Standardize on the exact same operating systems. Outsource security and core infrastructure to a tiny cartel of third-party vendors because it looks great on a balance sheet.
It is efficient until it isn't.
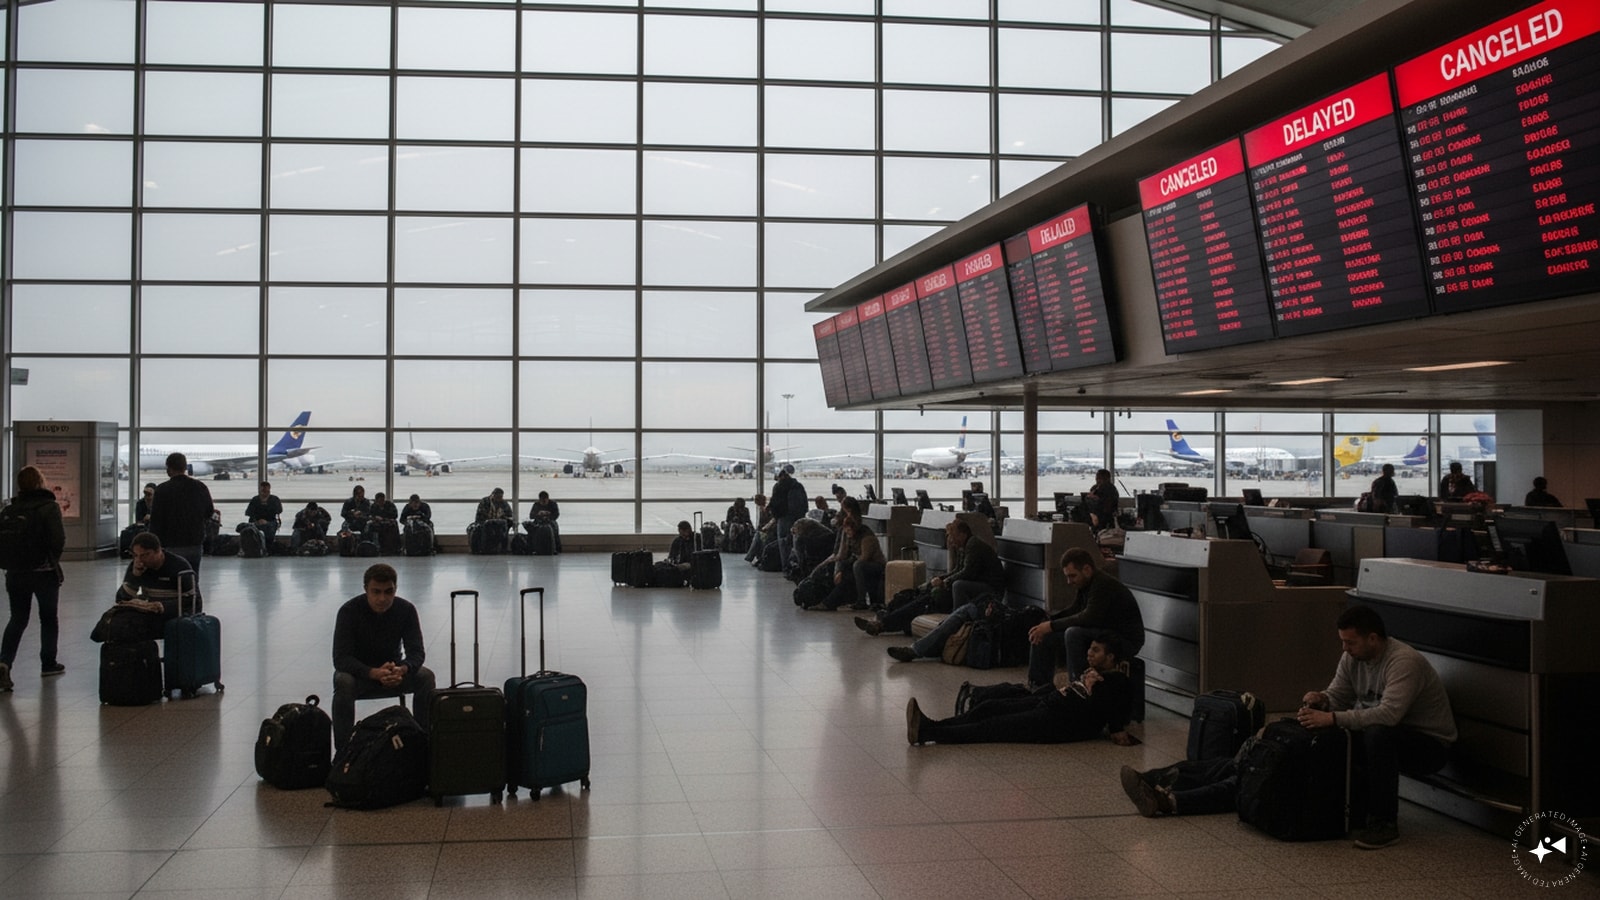
When millions of Windows machines simultaneously crash into the dreaded blue screen of death because a single automated sensor update failed basic validation logic, efficiency instantly turns into an existential liability. Airlines can't track flight crews, check-in kiosks lock up, and baggage handlers resort to pen and paper. The entire architecture breaks down not because of a sophisticated state-sponsored cyberattack, but because of a routine code update that slipped past quality checks.
Why Monocultures Invite Disaster
Biological ecosystems that rely on a single crop species are notoriously vulnerable to blight. Digital ecosystems behave the exact same way.
When the vast majority of critical enterprise infrastructure standardizes on the exact same software stack, a bug at the root level doesn't stay isolated. It ripples instantly across continents.
- Aviation: Flight operations grind to a halt because dispatch and tracking systems depend entirely on synchronized cloud uptime.
- Healthcare: Elective surgeries get canceled and patient check-ins stall because local terminals can't authenticate network credentials.
- Public Services: Emergency response centers lose direct digital visibility, forcing dispatchers to scramble for backup analog channels.
The real issue isn't that software fails. Software always fails eventually. The crisis lies in our complete lack of functional alternatives when it does. We have systematically dismantled analog redundancies under the banner of progress, leaving very little margin for error when the digital backbone hiccups.
Fixing the Architecture Problem
Preventing future system-wide collapses requires an uncomfortable shift in how enterprises think about risk. Companies can no longer treat software reliability as an outsourced checkbox handled entirely by vendors.
True resilience demands architectural diversity. It means building systems that can operate locally when cloud connections drop. It means demanding harsher validation testing for software updates that sit deep within system kernels. Most importantly, it means accepting that a little operational inefficiency is a fair price to pay to keep society from grinding to a complete halt every time a server farm stumbles.
We built a world that moves at the speed of light, but we forgot to install the brakes. Until enterprises prioritize actual structural resilience over blind optimization, these wide-scale breakdowns will keep happening.